Design Tuning Copilot
I built a Python tool that tunes a combat encounter with a hard enemy players should learn to beat. It simulates 4,800 fights, checks first wins, relapses, and time to kill, then asks an LLM for fixes. It resimulates every suggestion and rejects ones that make the fight too easy, and it hit every target in six tuning rounds.
Use an LLM for ideas, not for unverified balance changes.
I wanted a tool that could suggest an iteration when an encounter missed its targets, without treating the suggestion as a result. Every proposed change goes back through the same simulation and checks before I accept it.
- I simulate 4,800 fights across player styles and measure first wins, relapses, and time to kill.
- I identify where the encounter misses its targets and ask an LLM for a constrained change.
- I resimulate each suggestion and reject any result that makes the fight too easy.
- I keep only changes that meet the encounter targets, reaching every target in six tuning rounds.
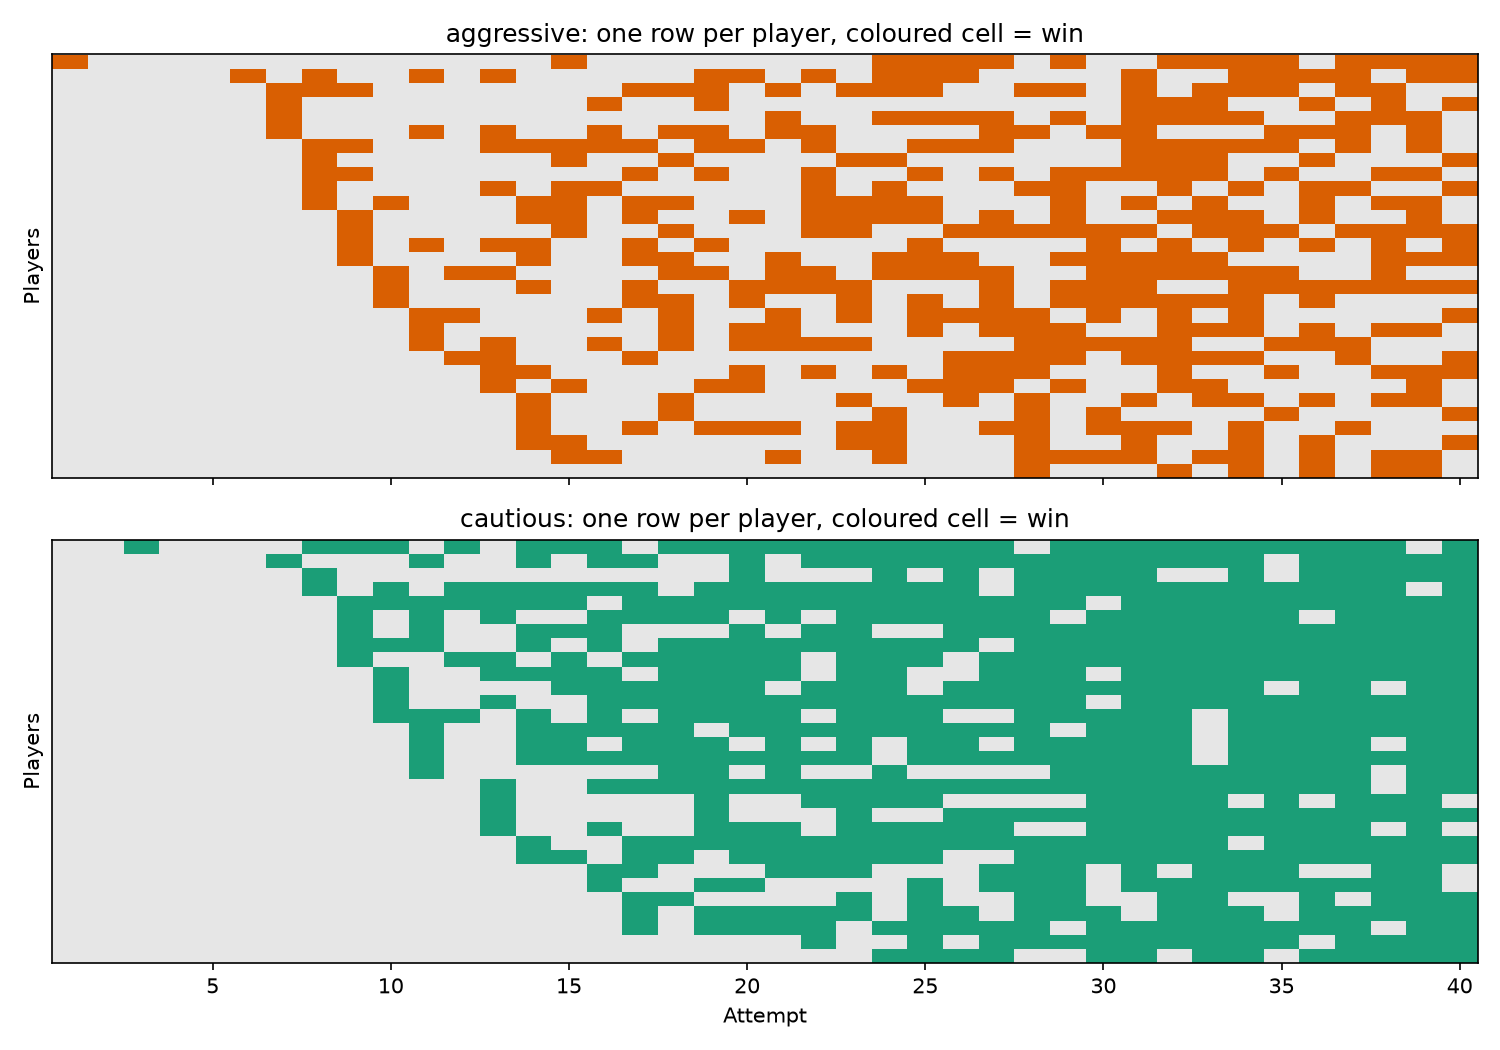
Every suggestion has to earn its place.
The tool records whether each round actually improves the learning curve without erasing the encounter’s challenge.
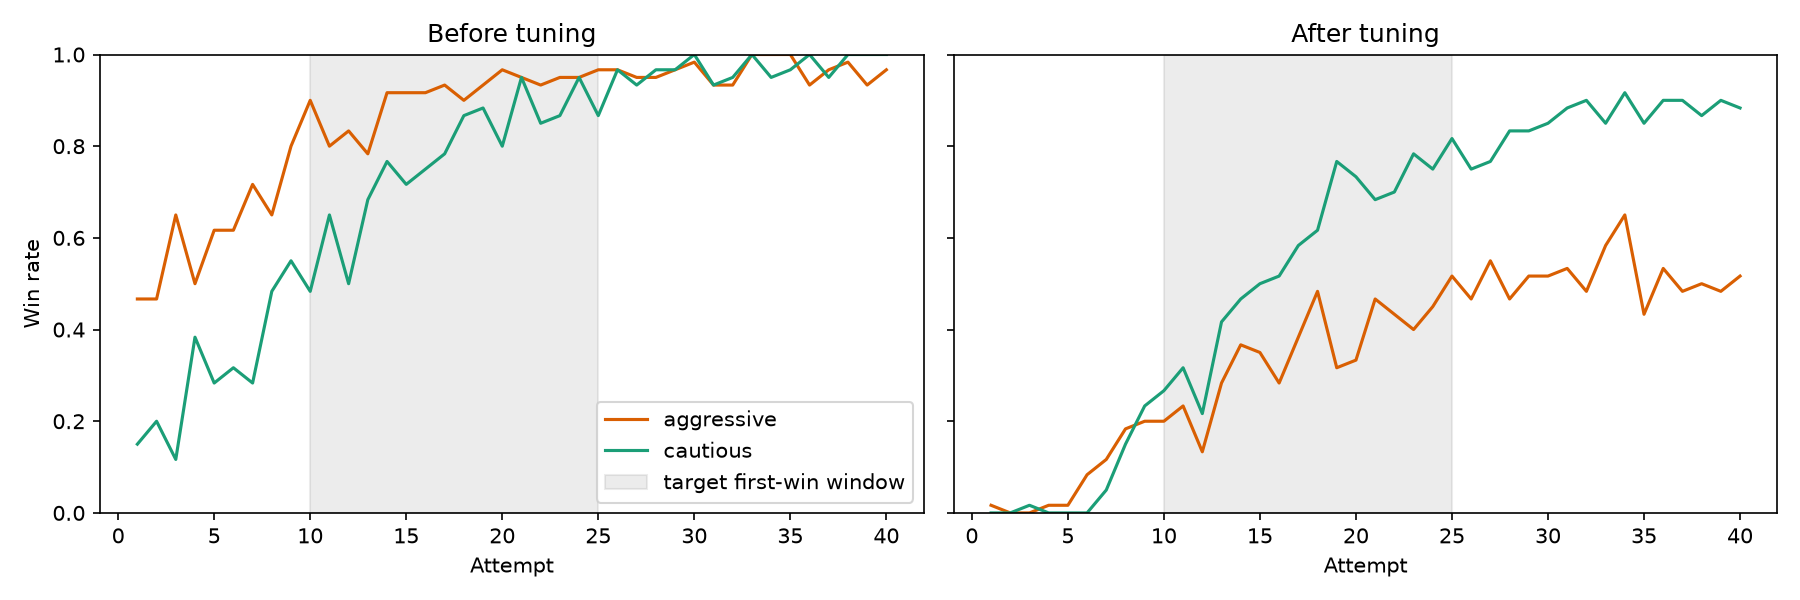
Checked, not trusted.
I use the LLM to propose a direction, then I make the simulation decide whether that direction is acceptable. That keeps tuning grounded in measurable first wins, relapses, and time to kill.
4,800 fights per tuning roundAll targets hit in 6 rounds